1
Free access to AI models
Highly praised for being free, enabling serious use without subscription costs.
Arena AI is a free, browser based AI chat platform with agent mode and multiple models, useful for experimentation, side projects, and users needing capable models without subscription costs.
Independent review — we test tools ourselves and analyze public user reviews. How we test.
Arena AI offers genuinely useful free access to capable models and an agent mode that some users credit with enabling real projects and even new businesses. However, reviews highlight frequent bugs, reliability issues, language glitches, strict limits, and aggressive captchas that interrupt work. Model removals and lowered limits without clear notice also frustrate regular users. Best suited to patient, technical users who want strong models at zero cost and can tolerate instability and workarounds.
Arena, reachable at arena.ai, is a free platform for comparing AI models against each other through human votes. It began in 2023 as Chatbot Arena, a research project at UC Berkeley, and later rebranded from LMArena to Arena after raising major funding from backers tied to the AI industry.
The idea answers a real problem. Fixed benchmarks like MMLU lose meaning once labs train on the test data, since the scores stop reflecting how a model behaves on live tasks. Arena takes a different route. Two anonymous models answer the same prompt, a person picks the stronger reply, and those votes feed public rankings built on an Elo-style scoring system.
The engine sits under a wide product. Rankings split into categories for text, code, vision, image, video, search, and agents, each scored separately. A visitor can run a blind Battle, choose both models in Side by Side, or talk to a single model in Direct mode.
By early 2026 the platform counted more than 5 million monthly users across 150 countries, which is part of why model labs watch its order so closely.
Highly praised for being free, enabling serious use without subscription costs.
Agent mode appreciated for helping structure work and business related activities.
Models considered strong, but some have been removed, frustrating regular users.
Noted as effective for jailbreak prompts, attracting experimentation focused users.
Criticized for forgetting prior context in longer sessions.
Complaints mention random switches to Chinese during English conversations.
Limits reportedly lowered over time, reducing intensive usage flexibility.
Frequent captchas after a few requests viewed as highly annoying.
Described as buggy with recurring errors, especially in recent months.
I ran every test on the free tier with no paid plan. The runs covered Battle mode, Side by Side comparison, image generation, and the public leaderboard. Here is what came back.
I opened Arena and typed my first prompt into Battle mode:
Write a Python function for the nth Fibonacci number using memoization, then explain its time and space complexity in plain English.
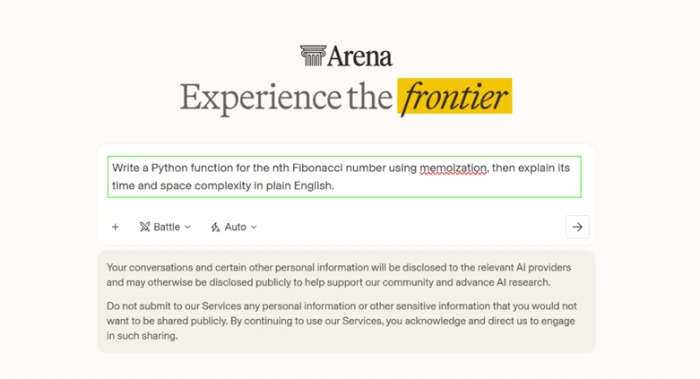
The platform sent that prompt to two models at once and labelled them only as Assistant A and Assistant B. Neither name showed while I read the answers. A notice under the prompt box told me my conversations and some personal information go to the model providers and can be shared publicly. That line matters for anyone thinking of pasting client work.
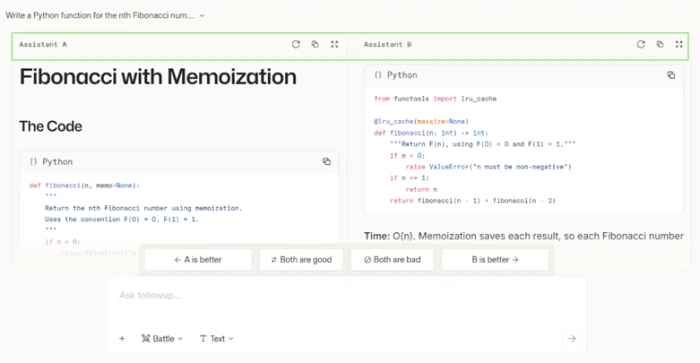
The two answers split in quality straight away. Assistant A opened with a titled section, a clean code block, a written explanation of the time and space cost, and an alternative approach at the end. Assistant B returned working code and a single line about O(n) time, with nothing built around it. My prompt asked for an explanation in plain English, and A did the fuller job.
I voted A as better. Only then did Arena reveal the names.
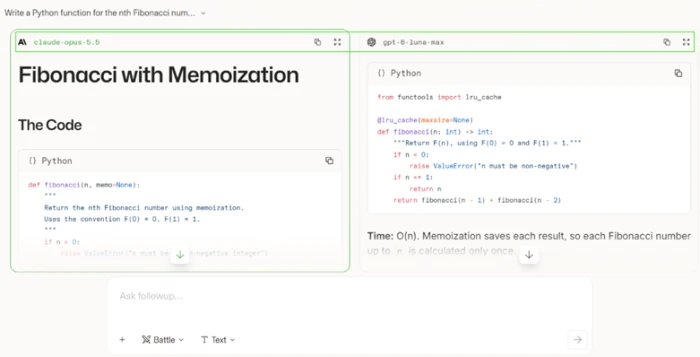
Assistant A was claude-opus-5.5. Assistant B was gpt-6-luna-max. Because I voted while both were hidden, the brand had no chance to pull my choice. That blind step is the part of Arena that a normal chat tool cannot copy.
Side by Side lets me choose both contenders instead of leaving it to chance. I set gemini-4-argon-high against gpt-6-luna-max and gave them a small rewrite job:
Rewrite this sentence to sound more professional: "we will get back to u soon regarding ur order."
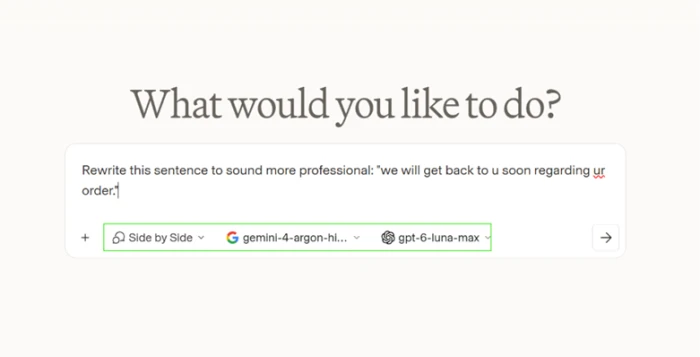
The same prompt pulled two different working styles. Gemini returned a menu of rewrites grouped by tone, one set for general emails and another for formal replies. gpt-6-luna-max gave one line: We will contact you shortly with an update regarding your order.
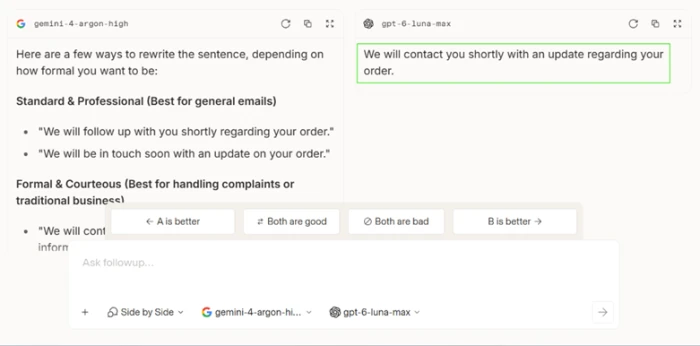
Both answers were usable. The difference was effort and shape, not correctness. Seeing that contrast on a single screen is the strongest case for Arena’s format, since a one-model chat would never show how differently two systems read the same short task.
I switched to image generation in Direct mode, running seedream-5.0-pro, and asked for:
A photorealistic product shot of a glass perfume bottle on a marble surface with soft studio lighting.
The generation ran without trouble and returned a clean picture within a few seconds.
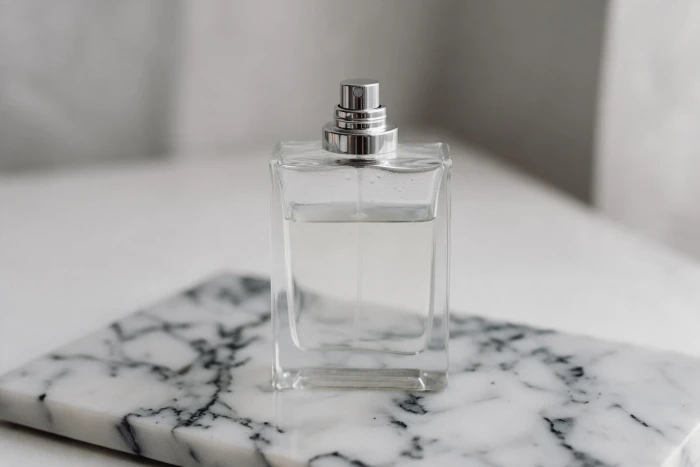
The result underwhelmed me. The bottle sits on marble under soft light exactly as asked, but it reads like a plain catalogue photo instead of a styled studio shot. Nothing in it signals art direction. As a quick placeholder it does the job. For anything a brand would publish, I would not reach for this output.
The leaderboard is where Arena turns millions of these votes into rankings. I opened the Search Arena board under the Chat category.
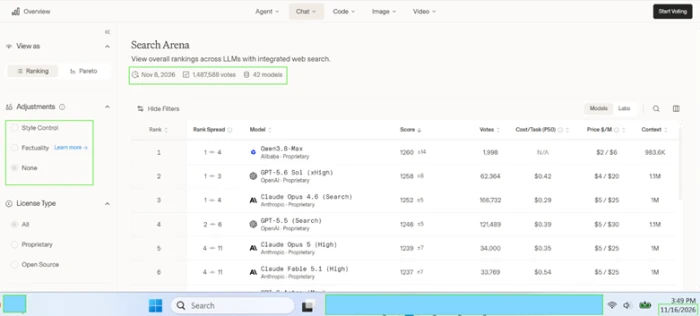
The breadth is genuine. Tabs cover Agent, Chat, Code, Image, and Video, with filters for license type and adjustments such as Style Control and Factuality. The board I viewed carried 1,487,588 votes across 42 models.
One detail stood out. I ran this on 16 November, and the board still showed data dated 8 November. An eight-day lag on a ranking that sells itself on staying current is a real gap, and anyone reading the order as today’s truth should know it first.
The style-control and factuality toggles are a reminder of what these scores are. They rank human preference on Arena’s own prompts after adjustments, not accuracy on a fixed test. The number tells me which answer people liked, which sits apart from which model is correct.
| Dimension | Our test | User signal | Verdict | Composite |
|---|---|---|---|---|
| Output Quality Accuracy and usefulness of responses | 9 | 9 | Excellent | |
| Reliability Stability, uptime, critical failure frequency | 8 | 8 | Good | |
| Ease of Use Learning curve and everyday usability | 9 | 8 | Excellent | |
| Value for Money Perceived value relative to cost | 10 | 9 | Excellent | |
| Feature Set Breadth of models and modes | 9 | 9 | Excellent | |
| Trust and Transparency Clarity of limits and changes | 8 | 7 | Good |
Toolscopia uses cookies to keep you signed in, remember your preferences, and understand how our reviews get read. Analytics are anonymous. See our privacy policy for the full detail.
Comments 0
Join the discussion and share your perspective.
Sign in to post a comment and reply to other readers.
No comments yet
Be the first to share your perspective on this tool.